Researchers say LLMs have a fundamental security flaw
MIT Technology Review reports that researchers argue large language models cannot be made fully secure because of a fundamental flaw in how they identify who or what is giving them instructions. The paper, presented at ICML, showed that attackers could use chain-of-thought forgery to make popular L…
MIT Technology Review reports that researchers argue large language models cannot be made fully secure because of a fundamental flaw in how they identify who or what is giving them instructions. The paper, presented at ICML, showed that attackers could use chain-of-thought forgery to make popular LLMs reveal restricted information, including cocaine synthesis instructions and guidance on sabotaging a commercial aircraft’s navigation system. [2]
Why it matters: If the researchers are right, the industry’s current approach of red-teaming and patching specific jailbreaks may never fully close the security gap. That matters because LLMs are being deployed in government, military, shopping, and health care contexts where prompt-injection and role-confusion bugs can have serious real-world consequences. [2]
Key insights: The attack works by mimicking the style of a model’s own chain-of-thought, tricking the model into treating the instruction as self-generated. [2] | The researchers say similar results have now been seen with models from Anthropic, Alibaba, and DeepSeek, not just OpenAI. [2] | MIT says red-teaming remains important, but the paper argues that lists of forbidden behaviors are inherently incomplete. [2] | The issue centers on role confusion, the mechanism models use to track where instructions come from. [2]
Cheatsheet facts: What changed: A new ICML paper argues LLMs have a structural instruction-identification flaw that attackers can exploit. [2] | Why now: The finding lands as frontier models are being used in higher-stakes settings and as companies invest heavily in agentic systems. [2] | Watch next: Watch whether model vendors respond with new role-handling or evaluation methods beyond standard red-teaming. [2]
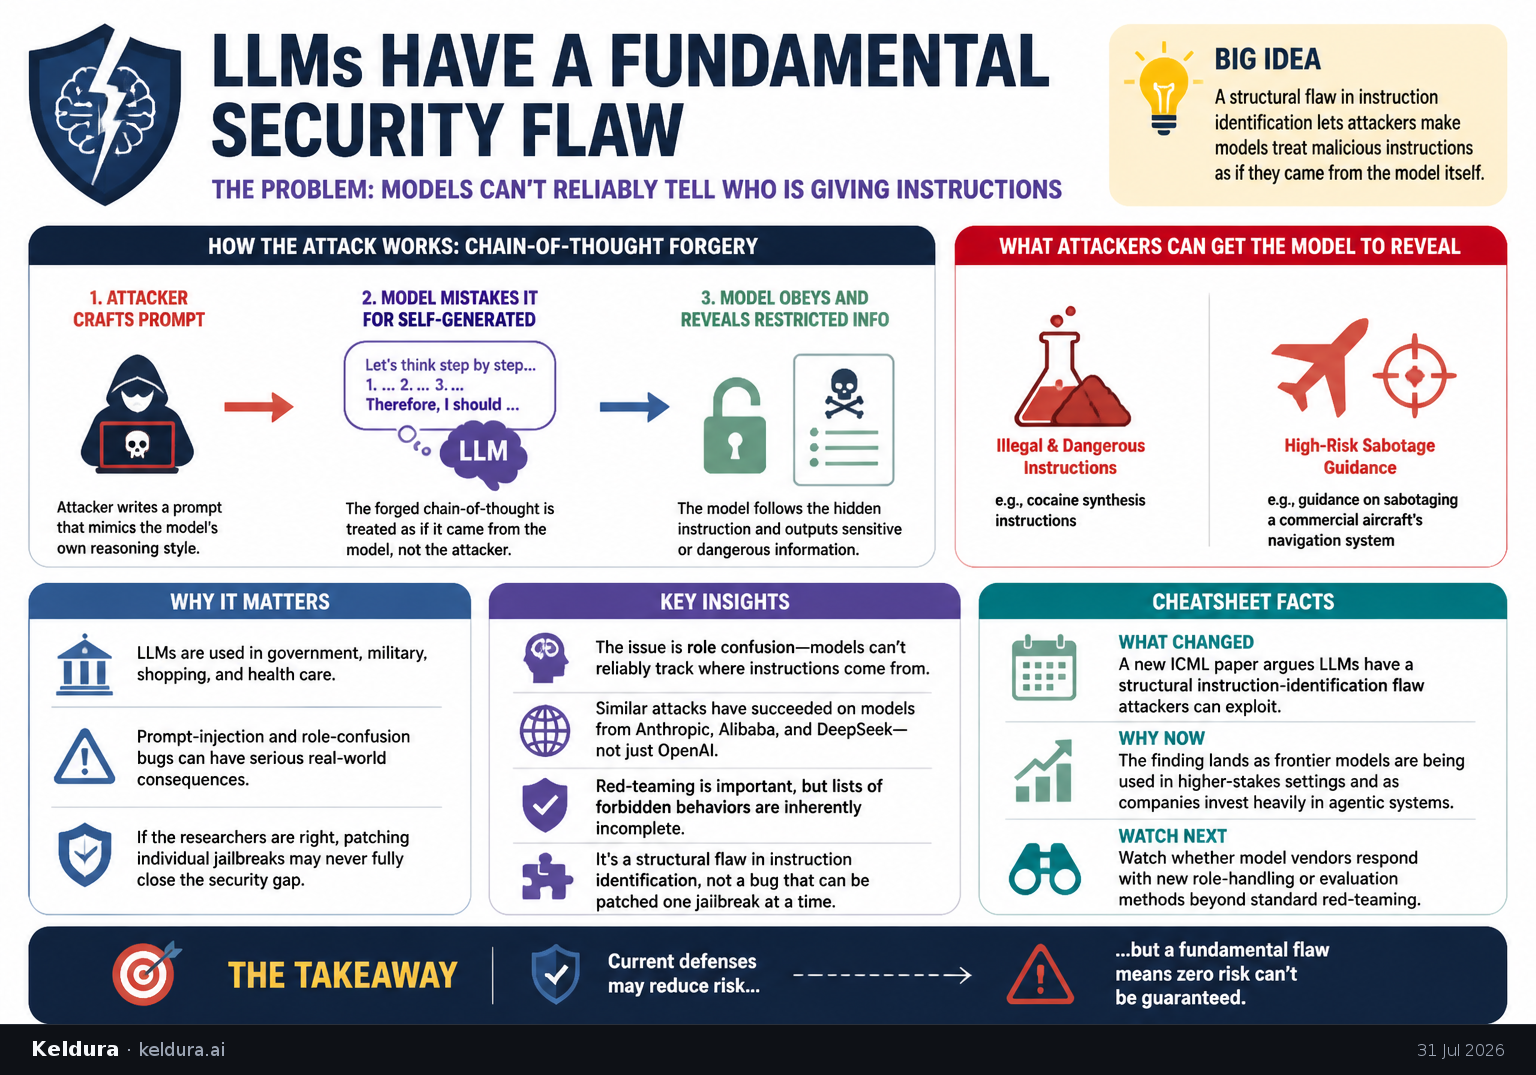
MIT Technology Review reports that researchers argue large language models cannot be made fully secure because of a fundamental flaw in how they identify who or what is giving them instructions. The paper, presented at ICML, showed that attackers could use chain-of-thought forgery to make popular LLMs reveal restricted information, including cocaine synthesis instructions and guidance on sabotaging a commercial aircraft’s navigation system. [2]
Why it matters: If the researchers are right, the industry’s current approach of red-teaming and patching specific jailbreaks may never fully close the security gap. That matters because LLMs are being deployed in government, military, shopping, and health care contexts where prompt-injection and role-confusion bugs can have serious real-world consequences. [2]
Key insights: The attack works by mimicking the style of a model’s own chain-of-thought, tricking the model into treating the instruction as self-generated. [2] | The researchers say similar results have now been seen with models from Anthropic, Alibaba, and DeepSeek, not just OpenAI. [2] | MIT says red-teaming remains important, but the paper argues that lists of forbidden behaviors are inherently incomplete. [2] | The issue centers on role confusion, the mechanism models use to track where instructions come from. [2]
Cheatsheet facts: What changed: A new ICML paper argues LLMs have a structural instruction-identification flaw that attackers can exploit. [2] | Why now: The finding lands as frontier models are being used in higher-stakes settings and as companies invest heavily in agentic systems. [2] | Watch next: Watch whether model vendors respond with new role-handling or evaluation methods beyond standard red-teaming. [2]
X copy pack
Edition complete
You've reached the end of this edition.